Key takeaways
- The same prompt returns different AI answers depending on who is asking and from where. Gumshoe.AI's research found a brand can show up in 60% of responses for one persona and 5% for another, which means a single "visibility score" is often hiding the real story.
- Locale testing is not translation. BotSee's methodology warns that a literal translation of an English prompt rarely matches how a German or French buyer actually phrases a question to an AI assistant.
- ChatGPT's web search layer appears to pick up IP-based location signals even though the model itself claims no geolocation access, which is a real contamination risk for anyone doing VPN-based locale testing.
- Engines behave differently as test benches: Perplexity cites a steady ~10 sources per response, AI Overviews about 10, ChatGPT only ~5 (per Promptwatch's sources-per-response data), and Copilot swings wildly, so pick your "control" engine carefully.
- Lock your prompt set and persona framing for a full measurement cycle before you touch anything, or your month-over-month trend line is comparing apples to a different fruit entirely.
Why one prompt set isn't enough anymore
I used to think AI visibility tracking was basically keyword rank tracking with a new UI. Pick 50 queries, run them weekly, watch the mention rate go up or down. Then I actually looked at what happens when you ask the same question as two different buyers, or from two different countries, and the numbers stopped making sense until I understood why.
Ask "best project management software for a 10-person agency" and you'll get one answer. Ask it again framed as a procurement director at a 500-person enterprise, and the model pulls different comparisons, different pricing framing, sometimes different vendors entirely. Gumshoe.AI, which builds synthetic personas specifically to probe this, has analyzed over 170,000 of them and found visibility swings of 55 percentage points between personas for the same brand on the same topic. That's not noise. That's the entire point of the exercise being missed if you only track one generic voice.
Locale adds a second axis of distortion. BotSee's agency reporting guide puts it bluntly: month-over-month AI visibility trends only mean something if you're running the same queries with the same persona framing each time, and that discipline has to extend across markets too. A brand with strong US citations can be nearly invisible in the French-language version of the same AI answer, because the source ecosystem AI pulls from is different. One market leans on product roundups and vendor blogs, another leans on local publishers or forums nobody outside that country reads.
Step 1: build persona cards, not just prompt lists
Growth analyst Kevin Indig's approach, which I think is the clearest framework out there, is a five-field persona card: job-to-be-done, constraints, success metric, decision criteria, and vocabulary. Skip the vocabulary field and you'll write prompts that sound like your own marketing copy instead of how a real buyer talks, which defeats the purpose.
A practical starting set for most B2B tools looks like:
- The evaluator (comparing 3-5 vendors, price-sensitive, asks "X vs Y" style questions)
- The problem-first searcher (doesn't know your category exists yet, asks "how do I solve [pain point]")
- The skeptic (already has a vendor, asking if they should switch)
- The technical buyer (asks about integrations, security, API limits)
Four personas, not three and not five. Resist the urge to round it to a tidy number just because it looks clean in a deck.
Stanford research cited by Indig found synthetic personas hit about 85% accuracy against real user behavior at a third of the cost of traditional panels, which is a genuinely good trade-off for most teams. But the Nielsen Norman Group has flagged a real limitation: AI chatbots can be sycophantic and don't always model human behavior well, so treat synthetic persona output as a strong directional signal, not gospel. If a result surprises you, sanity-check it against a handful of real customer interviews before you build a content roadmap on it.
Step 2: design locale variants properly, not via Google Translate
The single biggest mistake teams make is translating the English prompt set and calling it done. BotSee's country/language workflow is the clearest I've seen and worth copying almost verbatim:
- Pick 2-4 markets deliberately, tied to revenue, planned expansion, or competitive weakness. Don't track 12 countries just because you can.
- Build a shared core question set of 10-15 high-intent prompts that work across markets, plus 10-20 market-specific prompts per country sourced from actual sales call notes, Search Console queries, and local competitor pages in that language.
- Lock the prompt versions for a full measurement cycle before updating anything.
The reason step 2 matters so much: phrasing, specificity, and business vocabulary genuinely differ by market even when buyer intent is identical. A German buyer searching for the same category might use a more technical, compound-noun phrasing than the loose, conversational English version. If you don't localize natively, you're measuring your translation quality, not your actual AI visibility.
BotSee also illustrates the scale of the drop-off with a sample comparison: a brand with 62% mention rate and 38% citation rate in the US market dropped to 29%/11% in Germany and 18%/6% in France. That's the kind of gap a single global prompt set would completely hide.
| Market | Mention rate | Citation rate | What usually explains the gap |
|---|---|---|---|
| US (English) | 62% | 38% | Home market, most content, most backlinks |
| Germany (German) | 29% | 11% | Different source ecosystem, less native content |
| France (French) | 18% | 6% | Competitor set shifts to local/regional players |
Step 3: watch out for the geolocation contamination problem
Here's something that genuinely surprised me while researching this. There's a long-running OpenAI community thread where users report ChatGPT seeming to know their location within about 5 miles, despite the model insisting it has no access to IP or geolocation data. OpenAI's own explanation points to the web search tool itself: it appears to return region-influenced results based on network location, and those results then leak into the final answer even though the underlying model claims it can't see where you are.
What this means practically: if you're using a VPN or proxy to simulate asking from Berlin, your fan-out web searches probably will shift based on IP, which is exactly what you want. But any saved account memory, custom instructions, or logged-in context could leak through and contaminate what you thought was a clean, location-only test. If you're testing locale variations seriously, use logged-out or fresh sessions, not your personal account with months of chat history attached.
Tools built for this exist. SE Ranking offers a free ChatGPT Location Changer that spoofs a country without a full VPN setup, and services like Coronium run geo QA testing across 200+ countries using real mobile proxy IPs rather than datacenter VPN exits, which AI platforms are increasingly good at detecting and discounting.
Step 4: pick a stable engine as your test bench
Not every AI engine is equally reliable for A/B-style persona or locale testing, and this is where a lot of teams waste weeks chasing noise. Promptwatch's data on average sources per response is useful here: Perplexity cites almost exactly 10 sources per answer "day after day, with barely a decimal of movement," making it the most predictable engine for isolating whether a persona or locale change actually moved the needle versus just engine-level randomness. Google AI Overviews also cites around 10 sources and is fairly steady over time. ChatGPT cites a much scarcer ~5 sources per response, which means persona and locale variants there need to target tighter, long-tail prompts rather than broad category questions, because the inventory of winnable citation slots is smaller. Microsoft Copilot, meanwhile, swung from under 2 to nearly 17 sources per response within a few weeks according to the same dataset, which makes it close to useless as a baseline right now.
There's a second mechanical detail worth knowing if you're writing persona-framed prompts: Promptwatch's query fan-out data shows ChatGPT's fan-out searches dropped from an average character length of roughly 117 characters to about 53 characters between December and April, meaning the model is searching more like someone typing keywords than asking a full conversational question. If your persona prompts are long, natural-sounding sentences but your content headings are written the same way, the match between what the model actually searches for and what's on your page gets worse, not better. Write headings that read like short search queries.
Step 5: choose tools that actually support persona and locale segmentation
Most AI visibility trackers still treat geography as an afterthought. A few genuinely build for it:

Gumshoe AI starts by having AI models describe who they think your ideal customer is, then turns that into synthetic personas that hold real conversations with LLMs. It ships persona-by-topic visibility heatmaps, which is the clearest visual way I've seen to show a client why the same brand performs wildly differently depending on who's asking. Pricing runs $99/mo for Starter (weekly monitoring, one project) up to $299/mo for Pro (daily monitoring, all five audits).
Profound segments its multi-billion real-user-prompt dataset by intent, age, income, and region, which is a meaningfully different approach from simulated personas: it's measuring actual prompt volume and demographic skew rather than constructing a synthetic buyer. It recently added 30+ language support, which matters if you're tracking more than two or three markets.
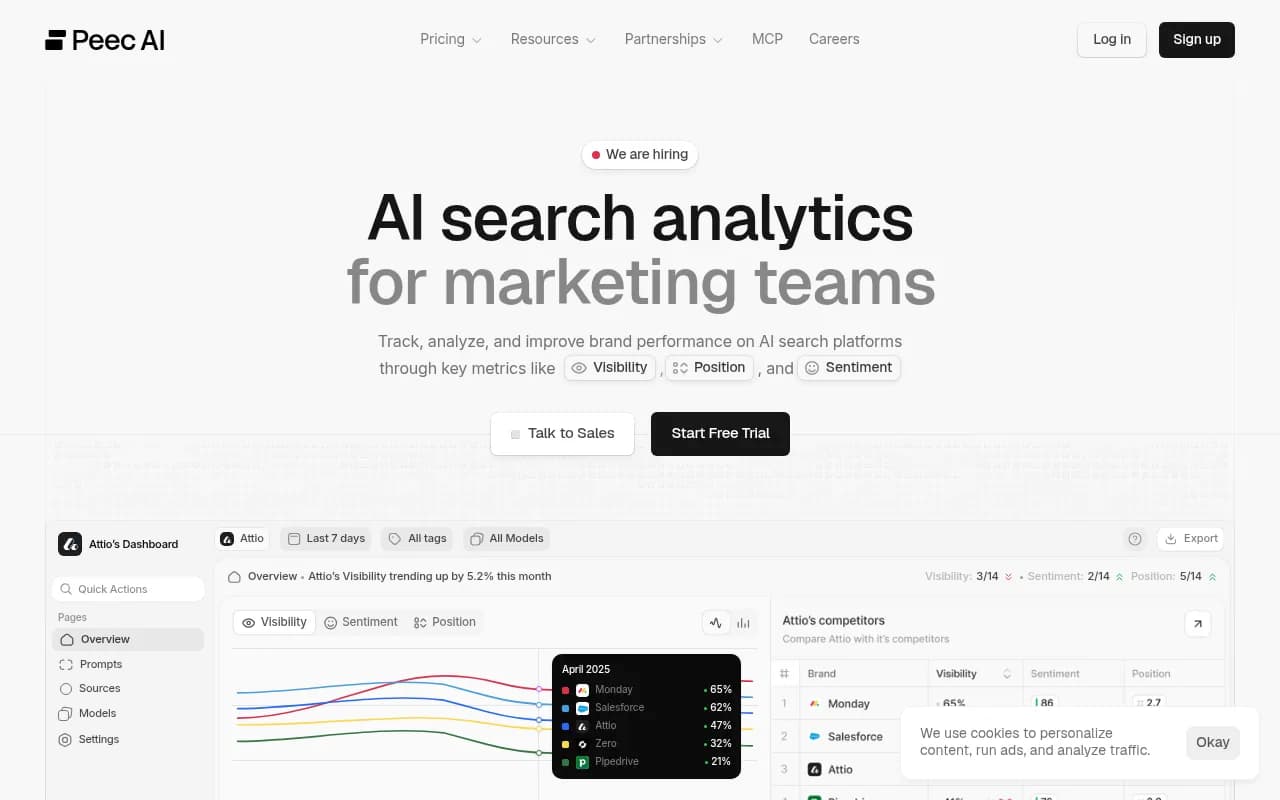
Peec AI tracks 14+ languages with country-level citation share breakdowns, and crucially doesn't charge extra per additional country or language, since pricing ties to prompt volume instead of geography. That's a meaningfully different cost structure from tools that treat each locale as a separate add-on.

Trackerly.ai lists prompt and web search localization as a feature even on its $27/mo entry plan, and its onboarding explicitly asks you to set localization settings as step one, before you even define competitors.
| Tool | Persona approach | Locale handling | Entry price |
|---|---|---|---|
| Gumshoe AI | AI-generated synthetic personas with heatmaps | Market-by-market prompts, manual setup | $99/mo |
| Profound | Real-user prompt segmentation by age/income/region | 30+ languages, demographic + geographic data | $99/mo |
| Peec AI | Manual persona prompts | 14+ languages, no extra cost per country | ~$103/mo |
| Trackerly.ai | Manual persona prompts | Localization settings built into onboarding | $27/mo |
| Promptwatch | Custom personas, country/state/city tracking | Multi-language, multi-region with custom personas | $95/mo |
If you're already tracking AI visibility broadly and want the persona and locale layer folded into the same platform that also handles crawler logs, content generation, and citation analytics rather than bolting on a separate point tool, Promptwatch supports custom personas and country/state/city-level tracking as part of its Prompt Intelligence feature set, alongside the crawler-log and content-agent capabilities that most dedicated persona trackers don't have at all. For a broader scan of options, the GEO software directory at bestgeosoftware.com lists dozens more worth comparing against your specific market list.
Step 6: build a measurement cadence you won't break
BotSee's query library guidance recommends keeping your first cohort to 30-50 queries total so a weekly review stays practical. That number felt small to me at first, but it's right: a 200-prompt matrix across 4 personas and 3 countries looks impressive in a spreadsheet and gets reviewed by nobody after week two.
A workable cadence:
- Week 1: lock persona cards and localized prompt sets, no edits allowed for the full cycle
- Weeks 2-4: run baseline, log mention rate, citation rate, and source quality per persona/locale combination
- Month 2: compare against baseline, only now start adjusting content based on gaps
- Ongoing: re-run the identical prompt set monthly, add new personas or markets only at the start of a new cycle
Store owner, update cadence, mapped URL, and the desired user action for each query, the same way BotSee recommends for its query library. Without that metadata, a six-month-old prompt list becomes unreadable the moment someone else on the team has to pick it up.
A quick sanity check before you ship this
The open question Kevin Indig raised publicly is worth sitting with: AI answers are probabilistic, we can't observe memory or account context from the outside, so do synthetic personas and locale simulations get us close enough, or does this eventually require real user panels? My honest answer is that synthetic testing is a very good early-warning system and a terrible final arbiter. Use it to find where to look, then validate the biggest gaps with a handful of real customers or local-market colleagues before you rebuild a content strategy around a synthetic signal alone.
If you want to see how AI visibility behaviour is trending more broadly, before you even get to the persona/locale layer, Promptwatch's research hub at promptwatch.com/data tracks citation share and crawler behaviour across ChatGPT, Gemini, Perplexity, and AI Overviews on a monthly basis, which is a useful baseline to compare your own numbers against.