Key takeaways
- Perplexity cites about 10 sources per answer, almost every day, according to Promptwatch's average-sources data. That stability makes it a good test bench for GEO work.
- Reddit figures for Perplexity range from 0.6% to roughly 47% depending on the study, the month and the method. Promptwatch's Sep 28 to Oct 4, 2026 data has Reddit at 0.86%, tied with LinkedIn.
- Social platforms together make up only 2.7% of Perplexity citations in that window. Most of the rest comes from editorial, brand sites, reference sources and niche specialists.
- The engines disagree with each other. One study found ChatGPT, AI Overviews and Perplexity share only 2 of their top 10 sources, so you need a plan per engine.
- The safe plan: earn tier-1 and niche editorial coverage, publish useful brand pages, stay present on Reddit and LinkedIn without over-weighting either, and track your own numbers weekly.
Why every Perplexity citation study seems to disagree
If you have read three articles on this topic, you have probably seen three different Reddit numbers. One analysis says Reddit is about 46.7% of Perplexity's top citations. Another says 20-24%. A March 2026 breakdown on r/AISearchLab put it at 17.3%. Agenzy's study of 2.28 million citations has it at 0.6%. Promptwatch's October 2026 data has it at 0.86%.
These are not all measuring the same thing. They differ in four ways:
- Time window. Reddit's weight in AI answers moved a lot during 2026. Semrush's Luke Harsel saw ChatGPT cite Reddit in close to 60% of prompt responses in early August 2025 and about 10% by mid-September, as quoted in the Agenzy study. Any Reddit number describes one window.
- Prompt set. A list built from US consumer questions looks nothing like one built from Lithuanian B2B queries. Agenzy's sample was 104 of 138 projects run from Lithuania.
- Definition of "top citations." Some studies count share of the top 10 or top 50 domains only. Others count share of all citations. The first inflates the big names.
- Retrieval layer. Some measure the real Perplexity interface, others use API outputs, and the two can differ.
My honest take: older articles saying Perplexity is "the community engine" were probably right when they were written. The current first-party data says that picture has faded. I would lead with the most recent, largest, real-interface dataset you can find, and re-check it quarterly.
What Promptwatch's data shows for Perplexity
The cleanest recent source is Promptwatch Data's social media citations report, covering Sep 28 to Oct 4, 2026 and built on 26B+ data points.
For Perplexity in that week:
- 2.7% of citations come from social platforms in total.
- LinkedIn and Reddit tie at 0.86% each.
- YouTube is at 0.79%, down from 2.67% in the earlier report.
- X peaks at about 0.1% of citations, and that peak happens to be on Perplexity.
- TikTok shows up only in AI Overviews, at 0.22%.
For context, ChatGPT's seven tracked social platforms total just 0.46%, and Google AI Overviews gets 12.2% of its citations from social platforms, about 26 times ChatGPT's share. Promptwatch's data on Reddit's drop in ChatGPT shows reddit.com falling from roughly 4% to 0.5% of ChatGPT citations on August 14, 2026.
| Engine | Share of citations from social platforms | Reddit share | Source |
|---|---|---|---|
| Perplexity | 2.7% | 0.86% | Promptwatch Data, Sep 28 to Oct 4, 2026 |
| ChatGPT | 0.46% | 0.09% | Promptwatch Data, same window |
| Google AI Overviews | 12.2% | 2.15% | Promptwatch Data, same window |
So in the most recent first-party window, Perplexity sits between ChatGPT and AI Overviews on social citations, and Reddit is not the dominant force it was often described as.
Citation density: about 10 sources per answer
One figure from Promptwatch holds up across studies: Perplexity cites almost exactly 10 sources per answer, every day, with barely a decimal of movement. ChatGPT averages about 5 on web-search responses, and AI Overviews about 10. One third-party index says 8.2 for Perplexity, which is in the same range but lower.
This has two practical effects.
- There are more slots to win. Ten citations per answer gives mid-authority and specialist sites a real path in, which matches Promptwatch's ChatGPT domain rank data, where DR 46-75 sites earned almost half of citations.
- It is stable enough to test against. When your citation pickup moves on Perplexity, it is more likely your content than engine noise.
The source types Perplexity cites
No one dataset gives a perfect domain-by-domain list, and I did not find a first-party Promptwatch report with one. Combining what the studies agree on, Perplexity's citations fall into these buckets:
| Source type | Examples | Notes |
|---|---|---|
| Tier-1 and fresh editorial | Reuters, NYT, Bloomberg, WaPo, FT, BBC, Guardian | Everything-PR reports press placements turning into citations within 24 hours to 7 days |
| Brand and company sites | Product, docs, comparison pages | Indexly puts about 18% of citations on brand-owned sites; Agenzy found company sites take around 47% across engines |
| Reference | Wikipedia | Present but less dominant than on ChatGPT in most studies |
| Community and social | Reddit, LinkedIn, YouTube | Small in Promptwatch's October data, much larger in earlier third-party analyses |
| Government and academic | NIH, PubMed, .gov, .edu | Over-indexed for health, finance and policy queries |
| Review and comparison sites | G2, Capterra | Relevant for B2B software comparison queries |
| Local business press | Regional business dailies | Agenzy's top Perplexity domain was a Lithuanian business daily |
That last line matters. In Agenzy's data, Reddit led ChatGPT, YouTube led AI Overviews, and a regional business daily led Perplexity. Your category and market decide your list more than any global ranking does.
Perplexity does not cite like ChatGPT
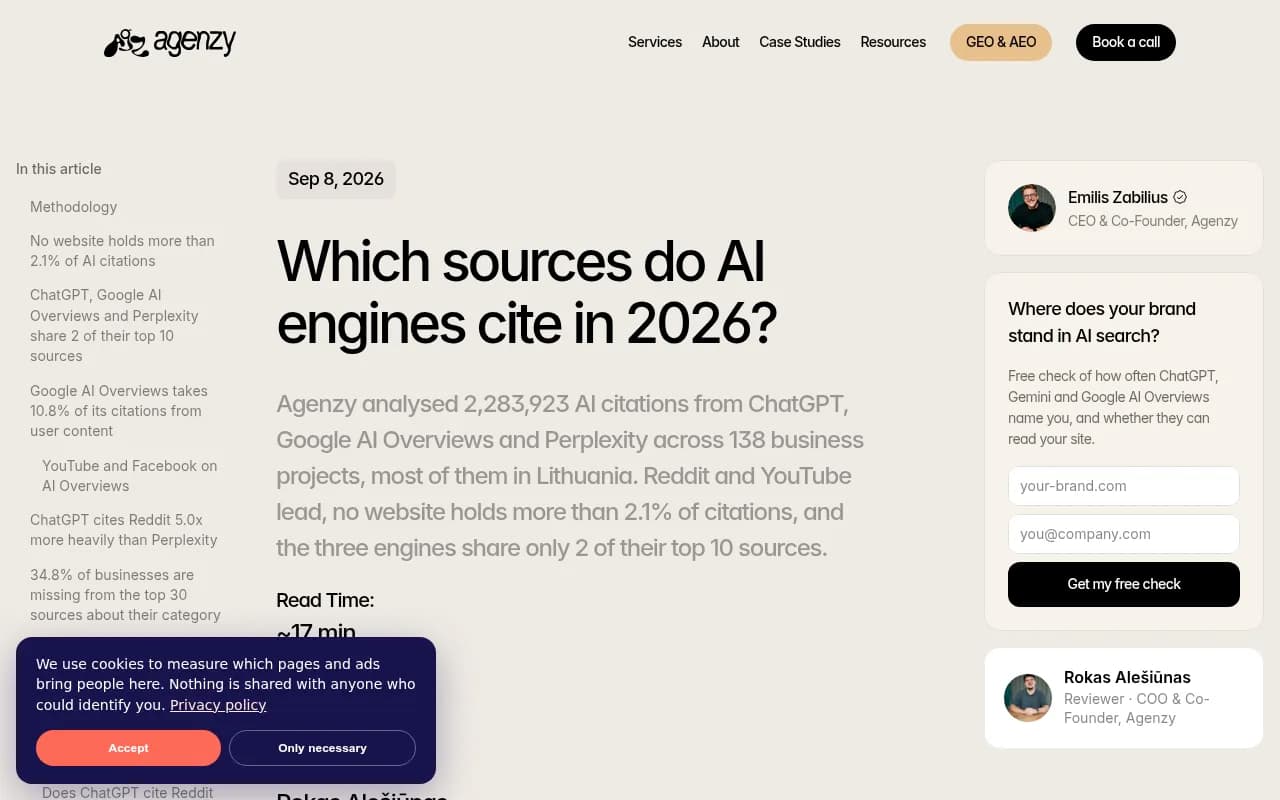
If you have worked on ChatGPT visibility, do not assume it carries over. Agenzy found that across 109 projects the three main engines shared only 2 of their top 10 cited sources for the same questions, and in 14.7% of projects not a single domain appeared in all three lists. Everything-PR claims only 11% of domains cited by ChatGPT are also cited by Perplexity. The numbers differ, the message does not.
There is also a pipeline reason. Perplexity crawls with its own bot, and ChatGPT has been described by Peec AI's Tomek Rudzki as running its own index while pulling from other providers. Different candidate pools plus different reranking mean different winners.
One more detail from Agenzy: Perplexity was the most selective at the citation step. For brand own sites, it cited them in fewer projects than ChatGPT (ChatGPT 85.5% at median rank 12), but higher up when it did. Being read is one hurdle, being cited another.
What brands can do
1. Check that Perplexity can read you
Check robots.txt, CDN and WAF rules for PerplexityBot and Perplexity-User. Promptwatch's AI crawler traffic data shows OpenAI falling from 94.8% to 79.8% of verified crawler requests between June and early September 2026, so other providers, Perplexity among them, gained share. If a provider is a big share in the benchmark but near zero in your logs, you are probably blocked. IP-verified crawler logs make this easy to confirm, and Promptwatch provides them alongside citation tracking.

2. Earn editorial coverage, not just owned content
The one finding every study agrees on is that most citations land on pages you do not own. Agenzy found that in its dataset brands' own sites earned 3.7% of citations while the competitors they tracked earned 16.9%. Pitch first-party data to the tier-1 outlets in your category, and to the specialist and regional publications that actually appear in your own citation lists. Fresh coverage seems to pay back fast on Perplexity, so time it around launches.
3. Be present on Reddit, but do not bet everything on it
The older advice to build a Reddit strategy is not wrong, but the weight is shaky. In the Promptwatch week, Reddit was under 1% of Perplexity citations. A reasonable approach:
- Contribute in specific buyer-decision threads, not subreddit homepages. One analysis said 99% of Reddit citations point at specific threads.
- Favor niche subreddits of 50K to 300K members over giant ones.
- Expect negative sentiment to be indexed just as readily as positive.
- Budget time for it as one channel among several.
If you want help finding threads, ReddGrow and CrowdReply are built for Reddit engagement, though platform rules and community norms apply and low-effort posting will backfire.


4. Post on LinkedIn too
Promptwatch's recommendation is to publish on LinkedIn as well as Reddit, since the two now earn the same share on Perplexity. Everything-PR argues Company Pages outperform individual posts on Perplexity, but treat that as a hypothesis to test, as I did not find first-party confirmation. Skip X for AI search planning; its share is about 0.1%.
5. Fix the pages that win citations everywhere
Promptwatch's content type data shows product pages at 22.4% of ChatGPT citations, ahead of landing pages and listicles. Its content half-life data says landing pages and docs stay cited longest while news loses half its pages within 36 days. Perplexity is not ChatGPT, but clear product, comparison and docs pages give you something durable to be cited. Date your content: Perplexity is reported to favor material from the past 12 months.
6. Cover the vertical sources
- B2B software: complete G2 and Capterra profiles with recent reviews.
- Health, finance, policy: link to and be co-cited with .gov and .edu sources.
- Local and regional: get into the business press that dominates your market's lists.
Measuring it
Because Perplexity cites roughly 10 sources every answer, it is a clean place to run a 90-day test. Pick 30 buyer-intent prompts, run them daily, record every cited domain, and note your own brand, competitors, and the top 30 sources for your category. Agenzy found 34.8% of businesses missing from their category's top 30 sources, so do not assume you are there.
Options in our catalog:
| Tool | Good for |
|---|---|
| Promptwatch | Tracking real Perplexity answers, citation and crawler data, then acting on gaps with content tools |
| Peec AI | Daily prompt tracking with source-level data; the platform behind the Agenzy study |
| Otterly.AI | Lower-cost brand monitoring |
| Profound | Enterprise monitoring and analytics |
| Ahrefs Brand Radar | Teams already living in Ahrefs |



For a wider view, the GEO software directory at bestgeosoftware.com lists more options. Whichever you pick, check that it measures real interfaces rather than only API responses, since user-facing citations can differ.
Caveats worth keeping in mind
- Perplexity's long tail is volatile. Top-10 positions are stable; positions 20-50 churn on a roughly 30-day rolling basis with the news cycle.
- Agenzy's sample is mostly Lithuanian projects. Everything-PR's index is a consolidation of other studies. Promptwatch's report covers one week.
- Conversion claims such as 3.1x the rate of Google organic come from third-party analyses. Verify them with your own analytics.
- Share-of-citation numbers move. Re-pull them every quarter, and see the Promptwatch Data hub for new reports.
Bottom line
Reddit being Perplexity's biggest source made a good headline, but the latest first-party data does not support it. What does hold up: about 10 citations per answer, a long tail of sources, editorial and brand pages doing most of the work, and very little overlap with other engines. Measure your own category on Perplexity this month, find the 10 to 30 domains that matter, and go get on them.