Key takeaways
- Prompt difficulty in GEO measures how hard it is to get your brand cited for a specific prompt, but there's no shared standard: some tools use a 1-5 score, others bolt difficulty onto topic-level keyword data, and a few don't score it at all
- Promptwatch ties difficulty to citation rate and prompt volume inside its Prompt Explorer, while Peec.ai uses a simple 1-5 score and Semrush and Jasper borrow difficulty logic from traditional keyword tools
- Difficulty scores are not comparable across platforms, the same way "keyword difficulty" in Ahrefs never matched Semrush's number either
- The more useful signal is usually the one underneath the score: citation rate, how many sources already answer the prompt, and whether query fan-outs spread the opportunity across sub-queries
- Pick one tool's methodology, track the trend inside it, and treat the absolute number as a rough filter rather than a KPI
Why prompt difficulty became a GEO metric at all
Keyword difficulty has been a staple of SEO tools for over a decade. It's a rough proxy for "how many strong domains already rank here, and how much backlink and content investment would it take to beat them." As GEO tools matured through 2025 and into 2026, several vendors tried to port that idea over to prompts: instead of "how hard is it to rank for this keyword," the question became "how hard is it to get cited when an AI model answers this prompt."
The problem is that ranking and citation are different mechanics. A keyword difficulty score is built on backlink profiles and domain authority, both of which are stable and measurable. A prompt's "difficulty" depends on how an LLM decides to construct its answer, which sources it pulls from, how it fans the prompt out into sub-queries, and whether it even cites anything at all. That's a much messier target, and it shows in how differently vendors have chosen to score it.
I'll say this up front: none of the difficulty scores below are wrong, exactly. They're just measuring different things and calling it the same name. If you're choosing a GEO tool based on how good its difficulty score is, you're optimizing for the wrong feature.
What "prompt difficulty" is actually trying to measure
Strip away the marketing and difficulty scoring in GEO tools is usually built from some combination of:
- How many distinct sources already get cited for that prompt (a crowded answer is harder to break into)
- The citation rate for the prompt across historical responses, i.e. how often the AI model cites anything at all versus answering from its own training
- Search volume or query volume feeding into the prompt, borrowed straight from traditional keyword data
- Domain authority or ranking strength of the sites currently being cited
- How many sub-queries the AI model generates when it fans the prompt out, since more fan-outs usually means more surface area to win a citation on
None of these are available through a single ground-truth API. Every vendor is approximating with whatever data pipeline they've built, which is exactly why the scores diverge.
How the major GEO tools actually score it
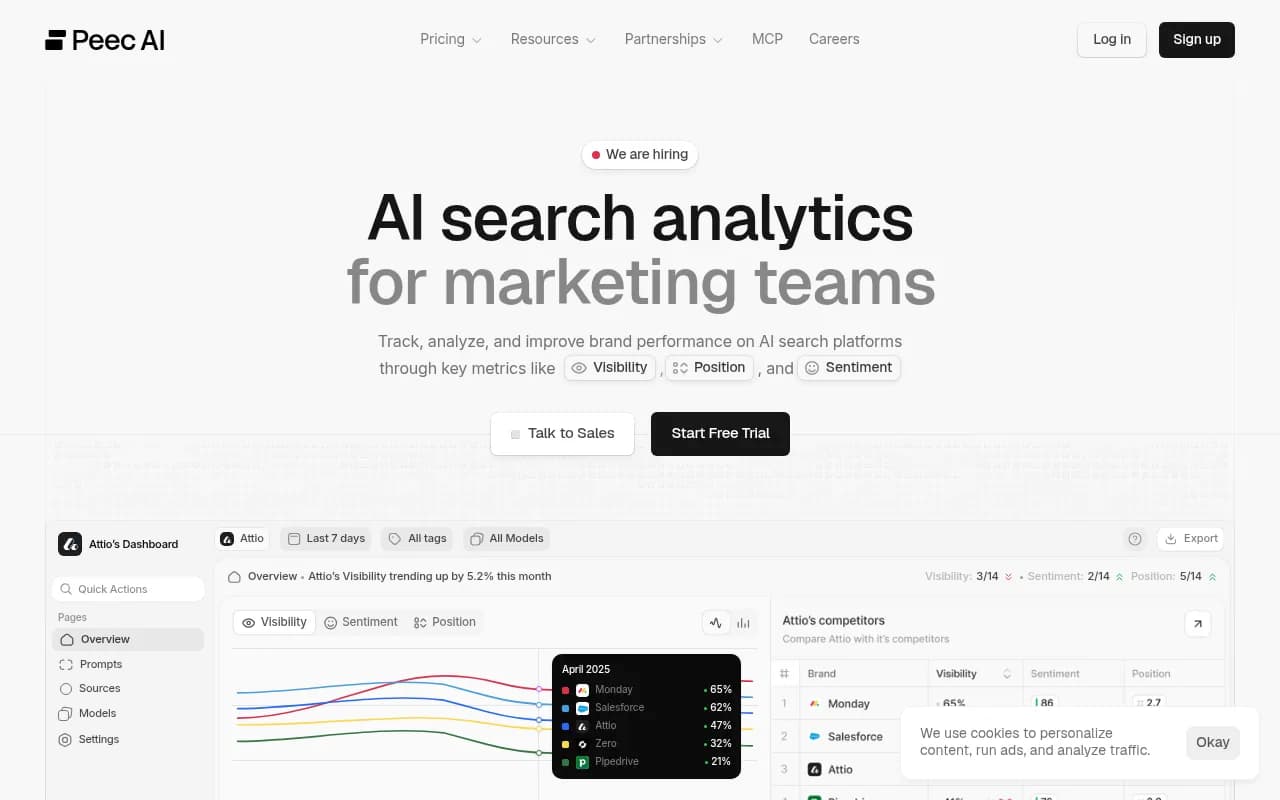
Peec.ai: a flat 1-5 score
Peec.ai keeps it simple with a 1-5 difficulty rating attached to each tracked prompt. It's quick to scan in a dashboard, but a flat five-point scale compresses a lot of nuance. Two prompts both rated "4" can have wildly different citation dynamics underneath, one might be crowded with ten competing sources, another might simply have low citation rates across the board because the model rarely cites anything for that query type.
Semrush and Jasper: borrowed from keyword tools
Semrush applies difficulty at the topic level rather than per prompt, which makes sense given its roots as a keyword research platform, but it means you're looking at a proxy one layer removed from the actual prompt behavior. Jasper takes a similar approach with its Query Planner, treating prompt difficulty more like a content-planning input than a live citation metric.
Both are useful if you already live inside those platforms for traditional SEO, but neither is purpose-built for how AI models actually decide what to cite.
Promptwatch: difficulty tied to citation rate and volume
Promptwatch's Prompt Explorer sits a prompt volume database on top of difficulty and citation-rate scores, and lets you build prompt sets four different ways: pulling from Google Search Console queries you already rank for, a DataForSEO keyword connection, AI-generated suggestions, or feeding in a single URL and having it build a prompt set from that page alone. The GSC route is worth calling out specifically, it's first-party data about what your actual customers search, rather than a model's guess at what people might ask.
The difficulty figure itself is derived from citation rate, how often a response for that prompt actually cites anything, rather than a flat competitive score. That matters because a prompt can look "easy" by volume but have near-zero citation rate across models, meaning the AI model almost never names a source at all, which makes it a poor target no matter how the difficulty number reads.
AirOps and Scrunch: fan-out and gap-based signals
AirOps leans on its Prompt Discovery and fan-out view, showing the actual sub-queries a model generates when answering a prompt, which gives you a difficulty signal by proxy: more fan-outs and more competing answers per sub-query generally means a tougher prompt to win. Scrunch ties difficulty more to its content-gap tooling, framing it around topic gaps rather than a standalone score.
Tools that skip difficulty scoring entirely
A chunk of the 22 GEO platforms tracked in Promptwatch's 2026 comparison of 21 GEO and AI visibility platforms don't score prompt difficulty at all, Profound, AthenaHQ, Searchable, Otterly.AI, Brandlight, and others focus instead on prompt volumes, competitor gaps, or citation trends without assigning a difficulty number. That's not necessarily a weakness. If the score itself is unreliable across the industry, skipping it and giving you richer citation and volume data instead might be the more honest choice.
Comparison table: how GEO tools handle prompt difficulty
| Tool | Difficulty scoring method | Granularity | What it's actually built on |
|---|---|---|---|
| Promptwatch | Difficulty + citation-rate score in Prompt Explorer | Per prompt | Citation rate and prompt volume database |
| Peec.ai | 1-5 flat score | Per prompt | Proprietary, undisclosed weighting |
| Semrush | Topic-level difficulty | Topic, not per prompt | Legacy keyword difficulty logic |
| Jasper | Query Planner difficulty input | Topic/content planning | Keyword-style competitive scoring |
| AirOps | Fan-out view as a proxy signal | Per prompt, via sub-queries | Query fan-out volume and competing answers |
| Scrunch | Gap-based, not a standalone score | Topic gaps | Content coverage comparison |
| Profound, AthenaHQ, Searchable, Otterly.AI | No dedicated difficulty score | N/A | Prompt volume and citation tracking instead |
Why you shouldn't compare difficulty scores across tools
This is the part people get wrong most often. A prompt scored "7/10 difficulty" in one tool and "3/5" in another aren't measuring the same underlying thing, so there's no honest way to convert between them. Promptwatch's own comparison research makes a similar point about visibility scores generally: a 31% share of answer in one platform isn't better than a 12% share in another, because engine coverage, prompt sets, and citation parsing all differ between vendors. The same logic applies one level down to difficulty scores specifically.
What you can do is pick one tool, understand its methodology well enough to know what moves the number, and track the trend over time inside that single system. If your difficulty score for a target prompt drops from 8 to 5 over three months because you've shipped content and picked up citations, that's a real signal. Comparing your 5 to a competitor's tool showing their prompt at a 6 tells you nothing.
What to actually look at instead of (or alongside) the score
If you're deciding where to spend content effort, difficulty scoring is a filter, not a strategy. A few things worth checking regardless of which tool's number you're staring at:
- Citation rate for the prompt across recent responses, not just whether your brand shows up, but whether the model cites anyone at all
- How many distinct domains currently get cited, and whether any of them are pages you could realistically outrank or outcite
- Query fan-out behavior, since a prompt that expands into five sub-queries gives you five chances to get cited instead of one
- Prompt volume, so you're not spending a week on content for a prompt almost nobody asks
Promptwatch's Content Agent pulls several of these signals together, drafting and publishing content aimed at specific citation gaps directly to a connected CMS, though I'd still want a human reviewing anything before it goes live on a brand's site.
A quick gut check before you commit to a tool
If prompt difficulty scoring is the single feature pulling you toward one GEO tool over another, pump the brakes for a second. Ask the vendor directly what the score is built on: is it citation rate, domain strength, fan-out volume, or something proprietary they won't fully explain? If they can't answer specifically, treat the number as decoration.
For a broader look at how 21+ platforms stack up on prompt tracking, citation trends, crawler logs, and content execution beyond just difficulty scoring, the directory of GEO software at bestgeosoftware.com is a reasonable next stop, and Promptwatch's own 2026 comparison of GEO and AI visibility platforms breaks down the full feature set across all of them in one table.
FAQ
Is prompt difficulty the same as keyword difficulty?
No. Keyword difficulty is built on backlink and domain authority data that's relatively stable. Prompt difficulty tries to capture how hard it is to get cited in an AI-generated answer, which depends on citation rate, fan-out behavior, and how the model chooses sources, none of which map cleanly onto a backlink graph.
Which GEO tool has the most transparent difficulty scoring?
Promptwatch publishes the clearest logic, tying its difficulty figure to citation rate and prompt volume inside the Prompt Explorer. Peec.ai's 1-5 scale is simple to read but doesn't disclose its underlying weighting in much detail.
Should I ignore difficulty scores entirely?
Not entirely, they're a decent first-pass filter for prioritizing which prompts to chase. Just don't treat the absolute number as gospel, and don't compare scores between two different tools as if they're on the same scale.